ARGUS
Every cluster watched. Every incident explained. Nothing changed without you.
Named for the watchman who never closed all his eyes at once.
Your clusters already report every failure; the trouble is that they report each one separately, in their own vocabulary, and briefly. ARGUS turns that into what broke, why, and what to do about it, across every cluster — and then stops, because nothing in your clusters changes until a person approves it.
Why it exists
The evidence is in the cluster. Putting it together is the job.
Today
- One node fails and every pod on it raises its own alert
- The warning that explained it has aged out before anyone reads it
- kubectl, dashboards, Argo, Helm and a runbook in five tabs
- A hand-patched fix that the next GitOps sync quietly reverts
With ARGUS
- One incident per cause, with what it took down listed under it
- Changes and events kept, and every incident’s history recorded
- The cluster, its map, its Git source and its metrics on one page
- The fix proposed where it will survive: a pull request against your repository
What it does
One console, from fleet view to fixed
Incidents with a cause
Faults that persist become incidents, grouped by what caused them. Each comes with a root cause in one sentence, the read-only calls behind it, and what was ruled out.
The whole fleet on one screen
Open incidents and their trend, who is waiting on whom, every node, capacity, certificate expiries, upgrade readiness, and each application with the version every cluster runs.
A map of every namespace
Ingress to Service to workload to pods, with incidents placed on the objects they are about. Open anything with its events, logs, metrics and YAML.
GitOps and Helm, understood
Argo CD and Flux sync and health with the failure parsed into a plain cause, drift against Git, and Helm releases with the incidents open against each.
Checks before things break
Posture checks with NSA/CISA and CIS labels, network policy coverage, certificate runways, upgrade blockers and node drain impact. Exceptions can live in Git.
Metrics, cost and rightsizing
CPU, memory, request rate, errors and latency per workload, traffic between workloads and cost per namespace, from the Prometheus you already run. Rightsizing from measured p95 usage becomes a change you approve.
Fixes that wait for you
Every change is signed, dry-run, bound to the object’s current version and approved by a person. Hands-off mode exists, and it is off by default.
Your AI tools, on the same evidence
Claude Code, Cursor and other MCP clients get the read-only tools ARGUS’s own investigations use, scoped to what you can see and recorded in the audit log.
Yours, on your infrastructure
Self-hosted, with your database, your sign-in and your choice of model. Clusters dial out to ARGUS; nothing in your network listens for us.
Inside ARGUS
The console, as our own engineers use it
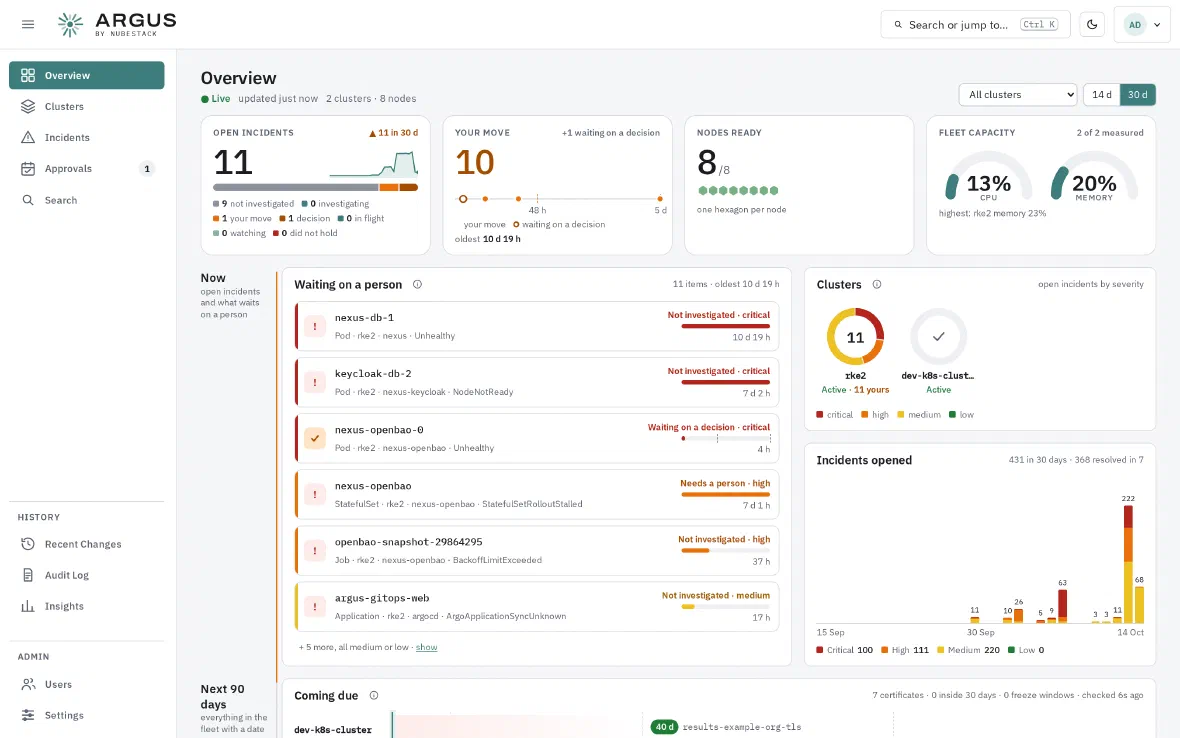
Every cluster on one screen
What is open and how it is trending, what is waiting on a person against its escalation deadline, every node, and fleet capacity — then ninety days of certificate expiries ahead.
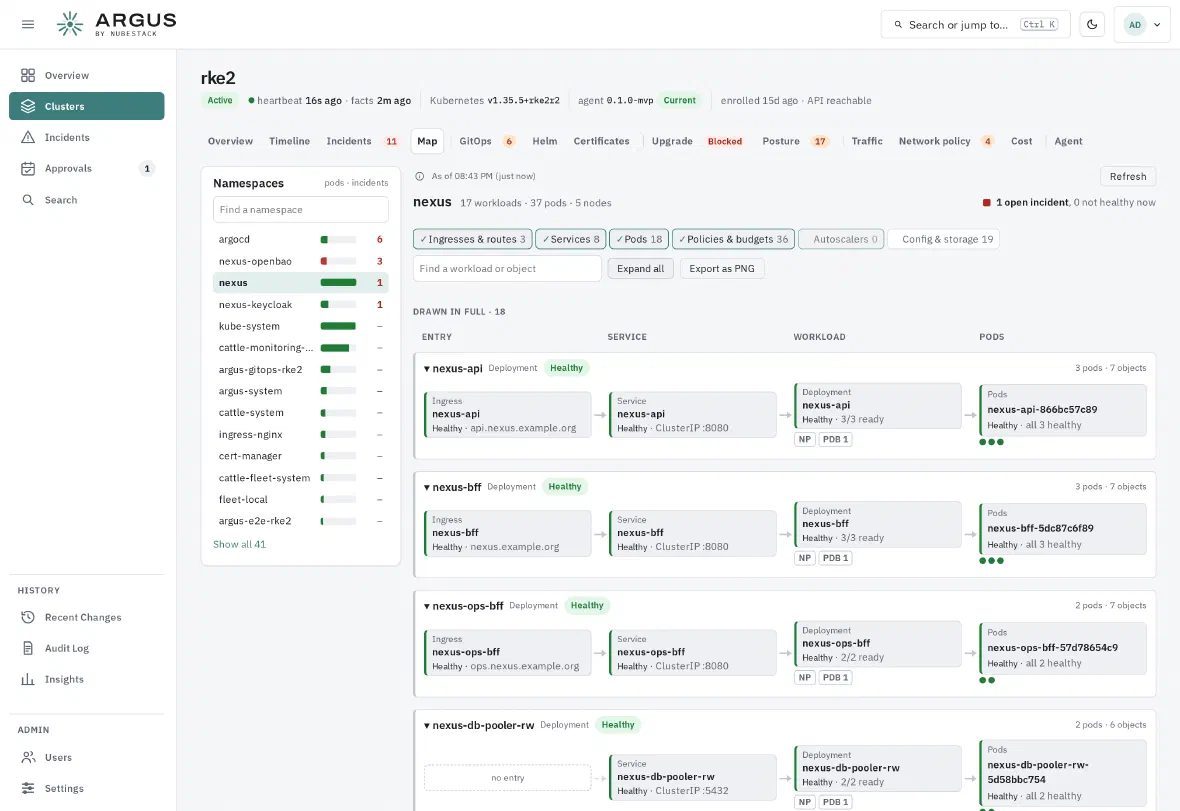
What connects to what
Each namespace as chains of entry, service, workload and pods. Healthy chains fold away so the broken one stands out.
What broke, and how far it has got
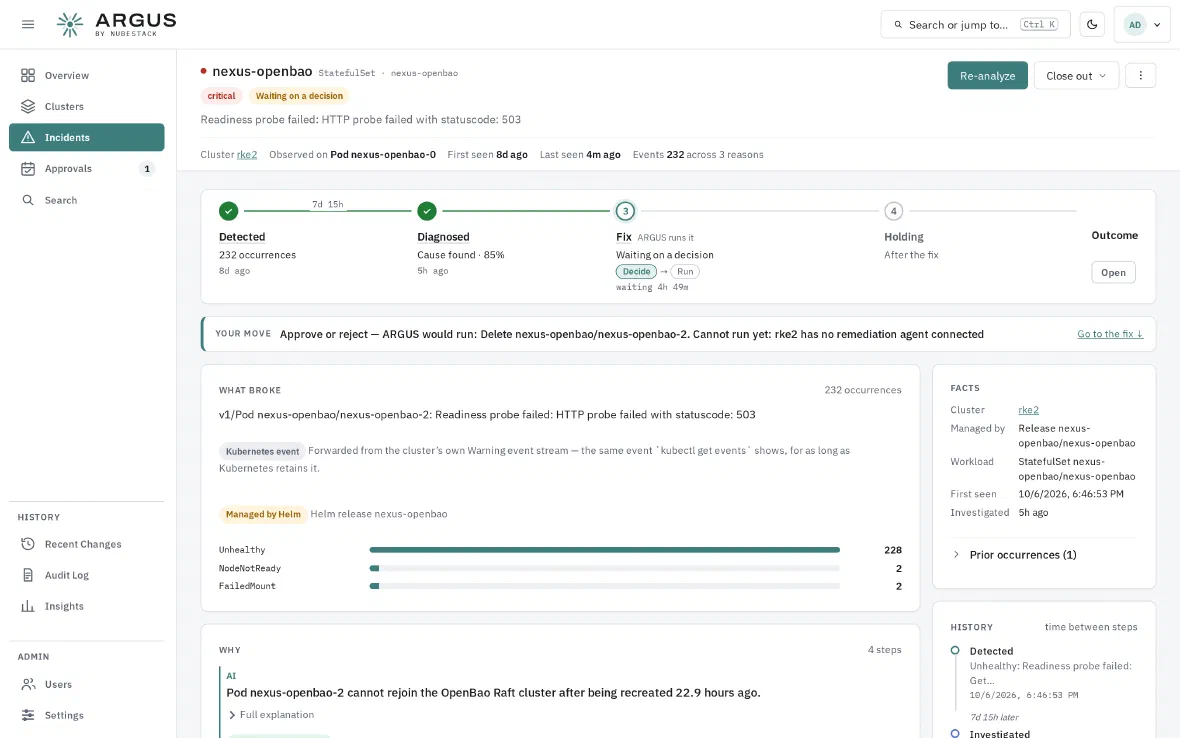
The object and its condition in the cluster’s own words, every reason reported against it, and a spine from detection to the outcome that says whose move it is.
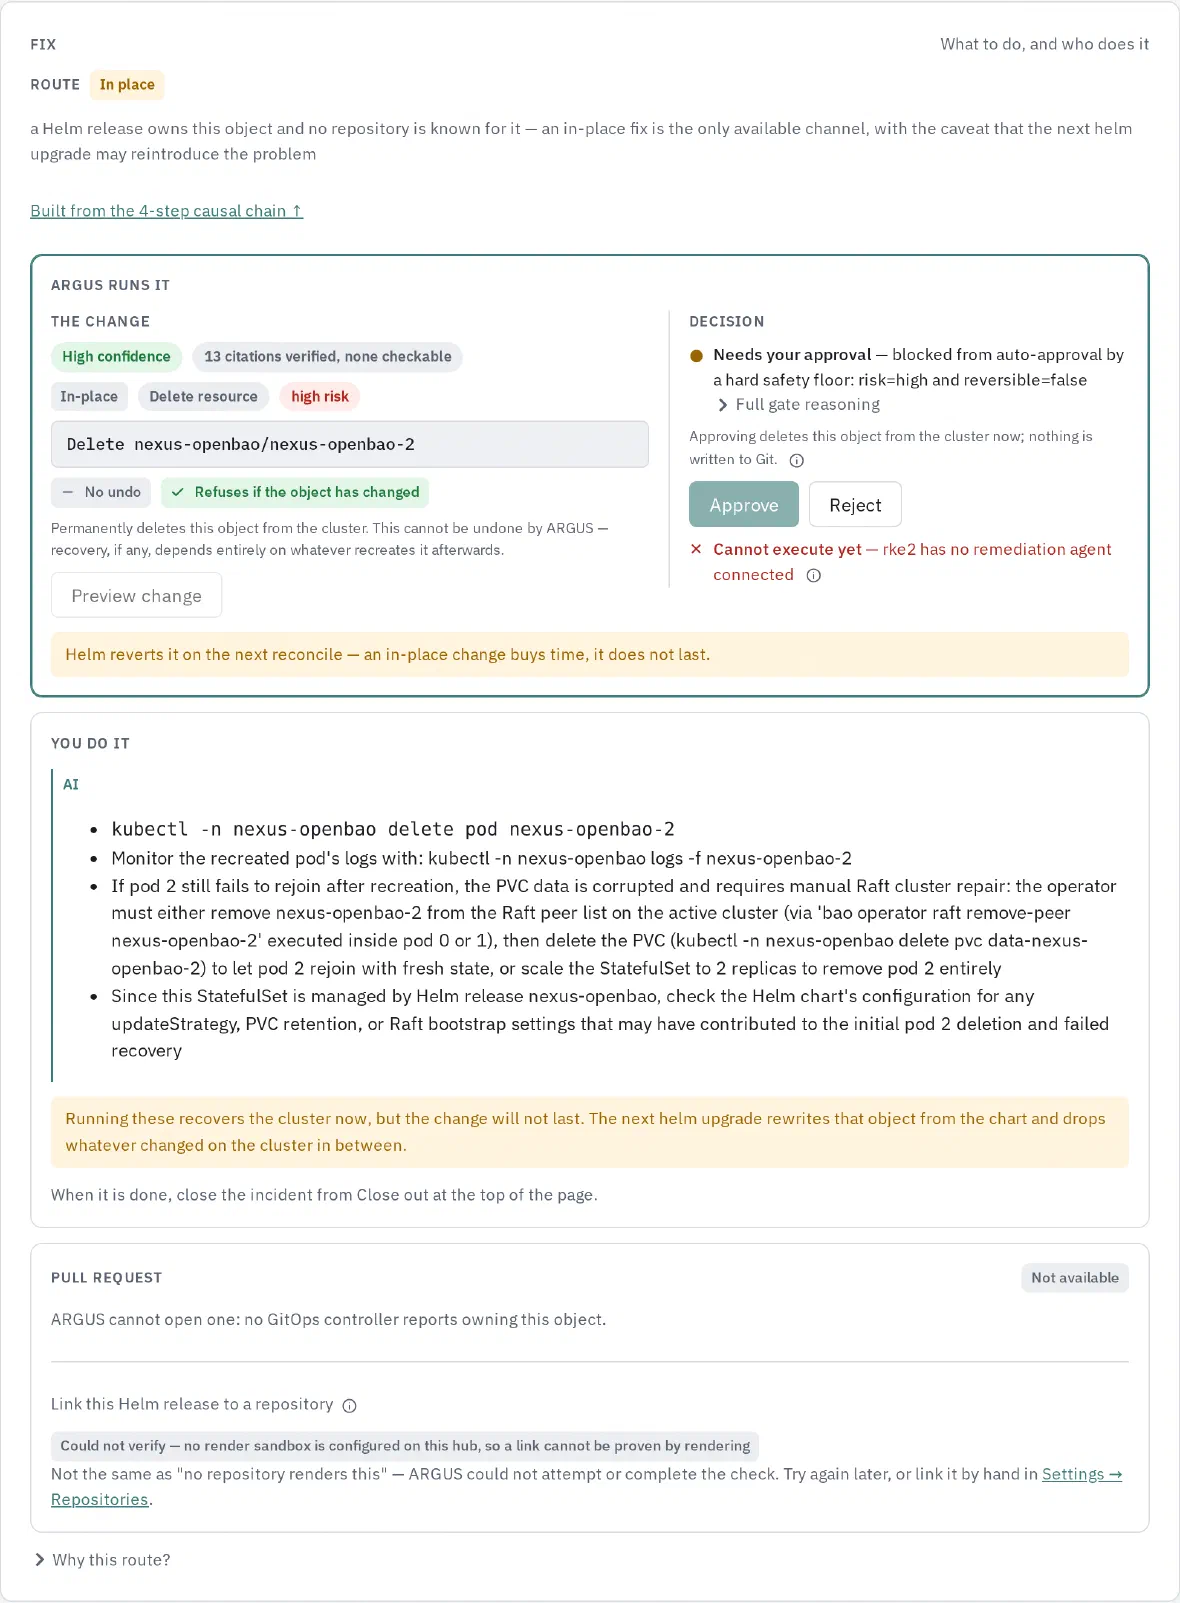
Where the fix belongs, decided by code
A pull request for what GitOps owns, a reviewed in-place change for what it doesn’t, or steps for a person — chosen from who owns the object before the model proposes anything.
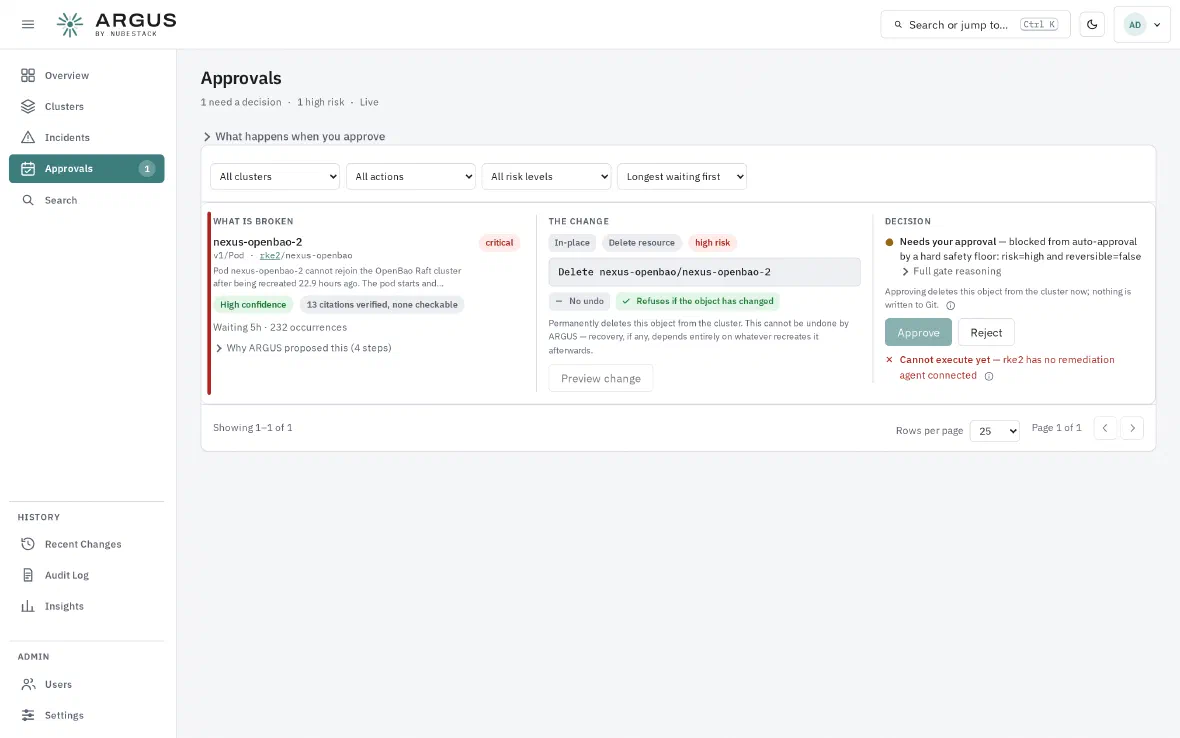
Nothing changes until you say so
What is broken, the exact change, and the safety rule that stopped it running on its own — side by side, in one queue.
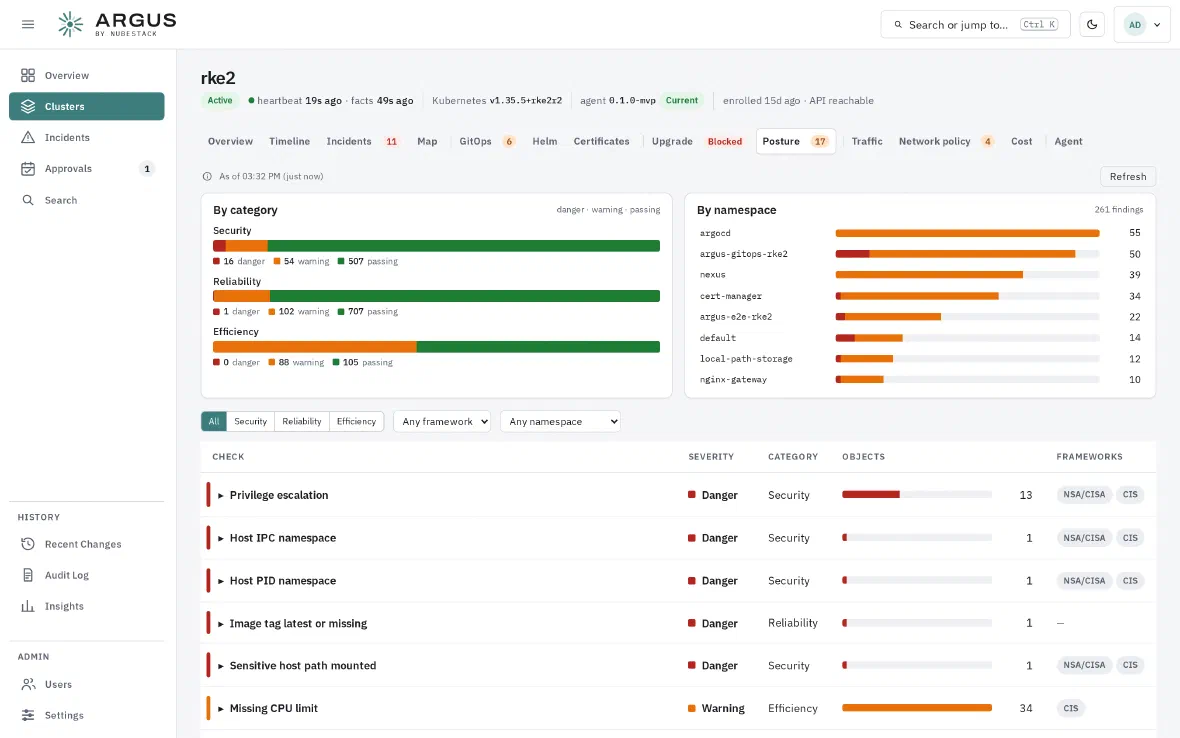
Risks, kept apart from incidents
Security, reliability and efficiency checks by category and namespace, with the framework each one comes from.
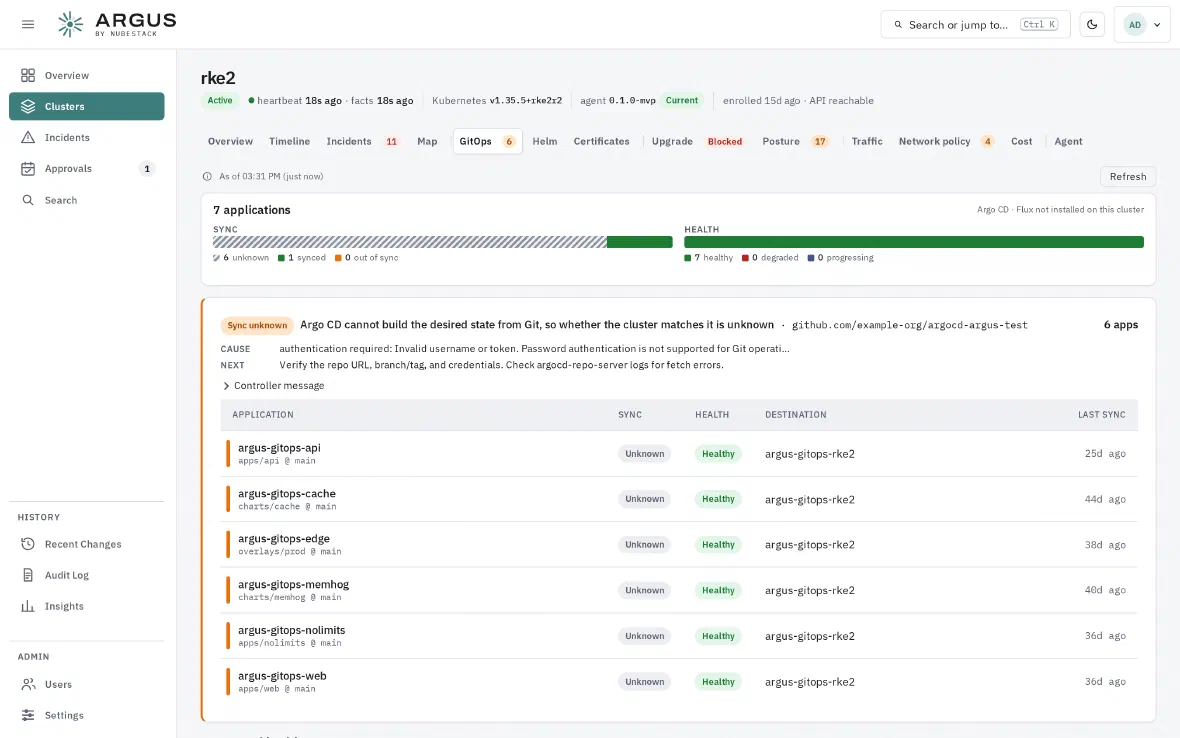
Argo CD and Flux in one place
Sync and health for every application, with a failed sync parsed into a plain cause and drift shown against what Git says.
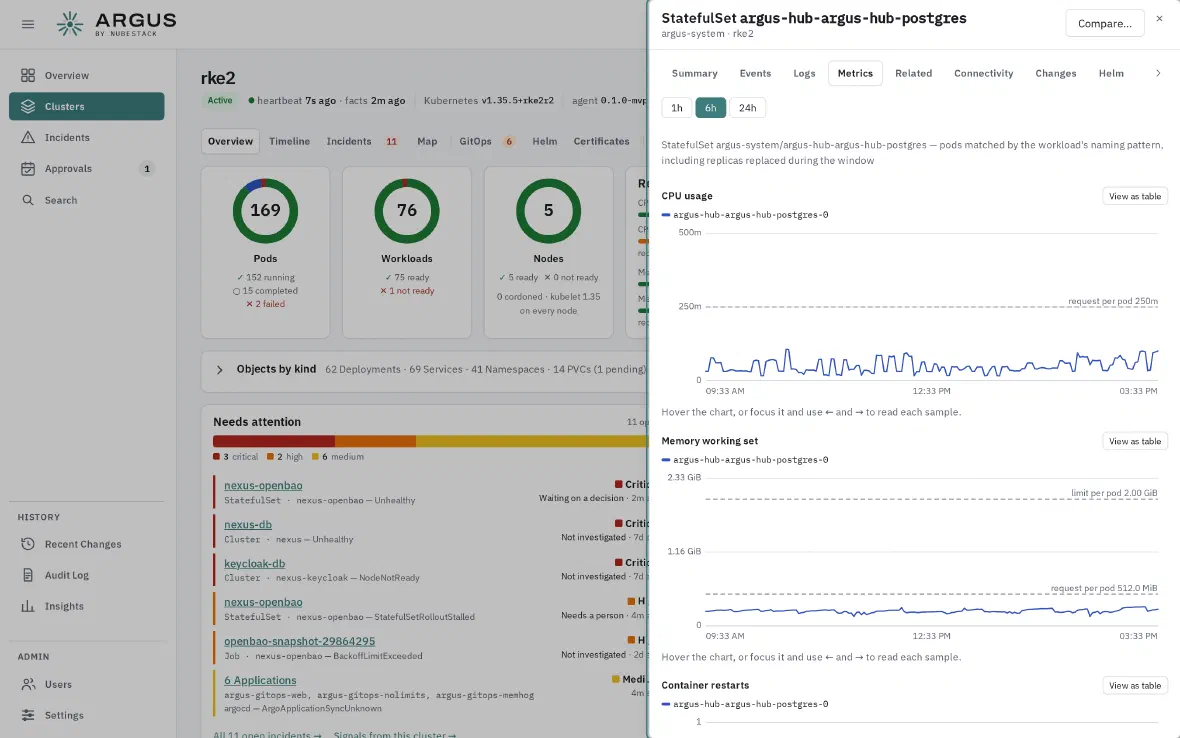
Usage against requests, pod by pod
CPU, memory, restarts and throttling from your own Prometheus, each pod drawn against its request and limit.
The loop
Four questions, answered in order
Notice
Every cluster, continuously. A problem has to persist before ARGUS calls it an incident, so nobody is woken for noise.
Group
One bad config behind twelve crash-looping pods is one incident, not twelve alerts.
Explain
The root cause in plain words, with the evidence that led to it — and what the investigation could not read, so a thin answer says so.
Fix
A pull request, a change to the cluster, or both. Proposed, dry-run, approved by a person, then watched until it holds.
ARGUS runs on your own infrastructure, and every cluster’s agent dials out to it. The agent that reads and the identity that writes are separate, and writing is opt-in per cluster.
Safety
Nothing changes until you say so
Hands-off mode is off by default, and most teams leave it that way.
Getting started
From an empty cluster to the first incident
- 01
Install the hub
One
helm installwith your hostname. It brings up the hub, its Postgres and an agent for the cluster it runs on, which connects by itself within a minute. - 02
Connect your other clusters
One
helm installof the agent chart per cluster, with a token from the console — or one fleet token for all of them, rolled out by Argo CD or Flux. Agents connect out through the hub’s own address; no inbound access is needed. - 03
Get it ready for the team
A short checklist in the console — a model, a second approver, somewhere for incidents to go, your AI tools — that ticks itself off as ARGUS sees each one in place.
GitOps first
The fix lands where it will survive
- A pull request against your sourceWhole files, as a diff, against the commit the controller actually synced. You review it and merge it. Nothing merges itself.
- Or a change straight to the clusterRestart, scale, resize, roll an image back — for what GitOps does not own, through a separate identity with a narrow grant.
- Then it watches it landAnd reopens the incident if the symptom comes back. A merged pull request closes its own incident.
Open source
Open source, and supported by us
- Open source
No licence fee, per cluster or per node
AGPL-3.0, so the tenth cluster arrives without a conversation about cost. Releases are signed and come with SBOMs and scan reports.
- Self-hosted
It runs where your platform runs
On your infrastructure, against your database, behind your own sign-in.
- Supported
Run by the people who built the platform
With our container platform services, the engineers who put the cluster together are the ones who tune the detectors on it.
Common questions
Worth asking early
Documentation
Everything, written down
Point it at one cluster and see what it finds
A single cluster, a fortnight, and a read-only start — no autonomy, no write access, just the incidents and the explanations. It is open source and one `helm install`, so the only cost is the afternoon it takes — or let us set it up as part of our container platform work.